AI Data Engineering Services
Build the Data Foundation Behind
Enterprise AI
Turn disconnected data sources into reliable, intelligent, and AI-ready data infrastructure, designed for analytics, machine learning, generative AI, RAG, and autonomous business applications.
Your AI Is Only as Reliable as the
Data Behind It
Most enterprises don’t have an AI problem. They have a data problem that AI has made impossible to ignore. Data is scattered across CRMs, ERPs, databases, SaaS platforms, APIs, and legacy systems that were never built to talk to each other.


Batch-oriented pipelines that can’t support real-time AI or agentic workflows

Inconsistent, duplicate, and low-quality data feeding models and dashboards

Missing lineage and observability, so no one can trace where a number came from

Data silos between departments that block a single, trusted view of the business

Large volumes of unstructured content sitting outside any governed pipeline

AI initiatives stalling because teams can’t access trustworthy, current data

Manual, spreadsheet-driven data preparation that doesn’t scale

Rising infrastructure and maintenance complexity across cloud and on-prem systems

Governance and security gaps that create risk as more systems touch AI
Engineering Data Infrastructure
for the AI Era
Redblox integrates modern data engineering and AI engineering principles to create data foundations for generative AI, RAG systems, machine learning, AI agents, agentic workflows, predictive analytics, real-time intelligence, business automation, and AI operating systems.
The goal isn’t just to move data from one system to another. It’s to make enterprise data:
- Accessible
- Reliable
- Governed
- Contextual
- AI-ready
- Actionable
Our AI Data Engineering Services
AI Data Architecture & Strategy
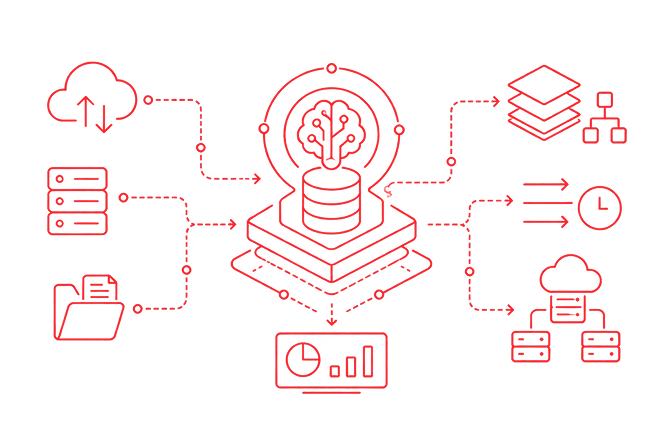
We begin by evaluating your present data architecture and AI readiness, including where data lives, how it moves, and where it breaks down. From there, we create a modern data architecture and platform strategy, which includes data domain design, batch vs. streaming decisions, and cloud or hybrid architecture built around real AI workloads rather than theoretical ones.
Intelligent Data Pipeline Engineering
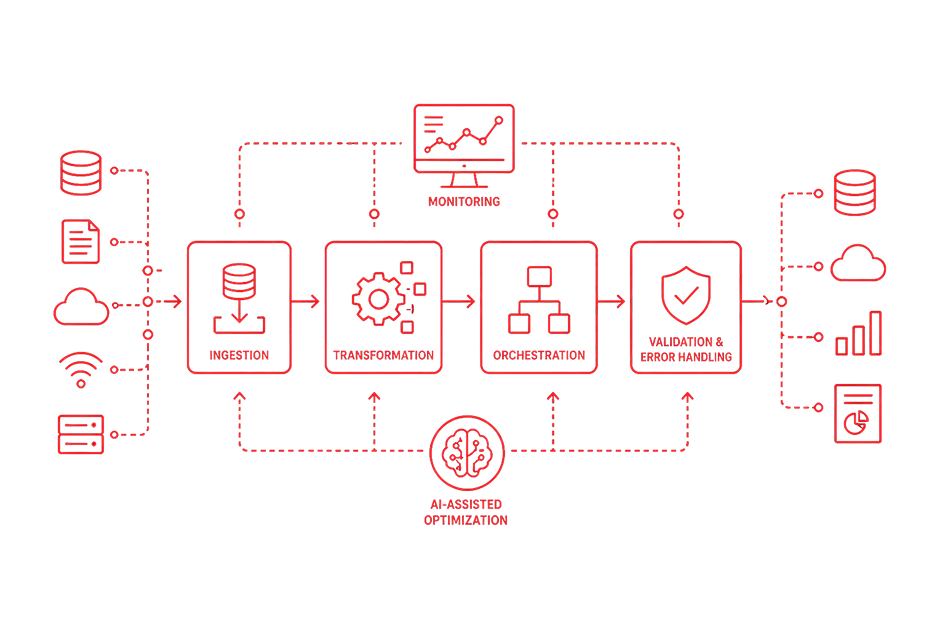
We create ETL/ELT pipelines with automated ingestion, transformation, and orchestration at their core. Pipelines are developed with schema management, validation, and error handling in mind, and they are continuously monitored and tuned with AI-assisted optimization to ensure their dependability as data volume and complexity increase.
From Enterprise Data to
Production-Ready AI
Enterprise Systems
CRM, ERP, Databases, SaaS, APIs, And Legacy Applications: Where Enterprise Data Actually Lives.
Data Integration
Unifying Fragmented Sources Into A Single, Connected Data Foundation.
Data Processing
Batch And Real-Time Pipelines That Clean, Transform, And Structure Data For Use.
Data Quality
Validation, Monitoring & Observability So Downstream Systems Can Trust What They Receive.
Business Outcomes
Faster Decisions, Reliable AI, And Infrastructure That Scales With Adoption.
Applications & Workflows
AI Agents, Copilots, Dashboards, And Automations That Run On That Foundation.
AI / ML / RAG
Feature Pipelines, Embeddings, And Retrieval Systems Built On Governed, AI-Ready Data.
Governed Data Layer
Access Controls, Lineage, And Classification Applied Before Data Reaches AI Systems.
AI Data Engineering
Use Cases
Enterprise RAG:
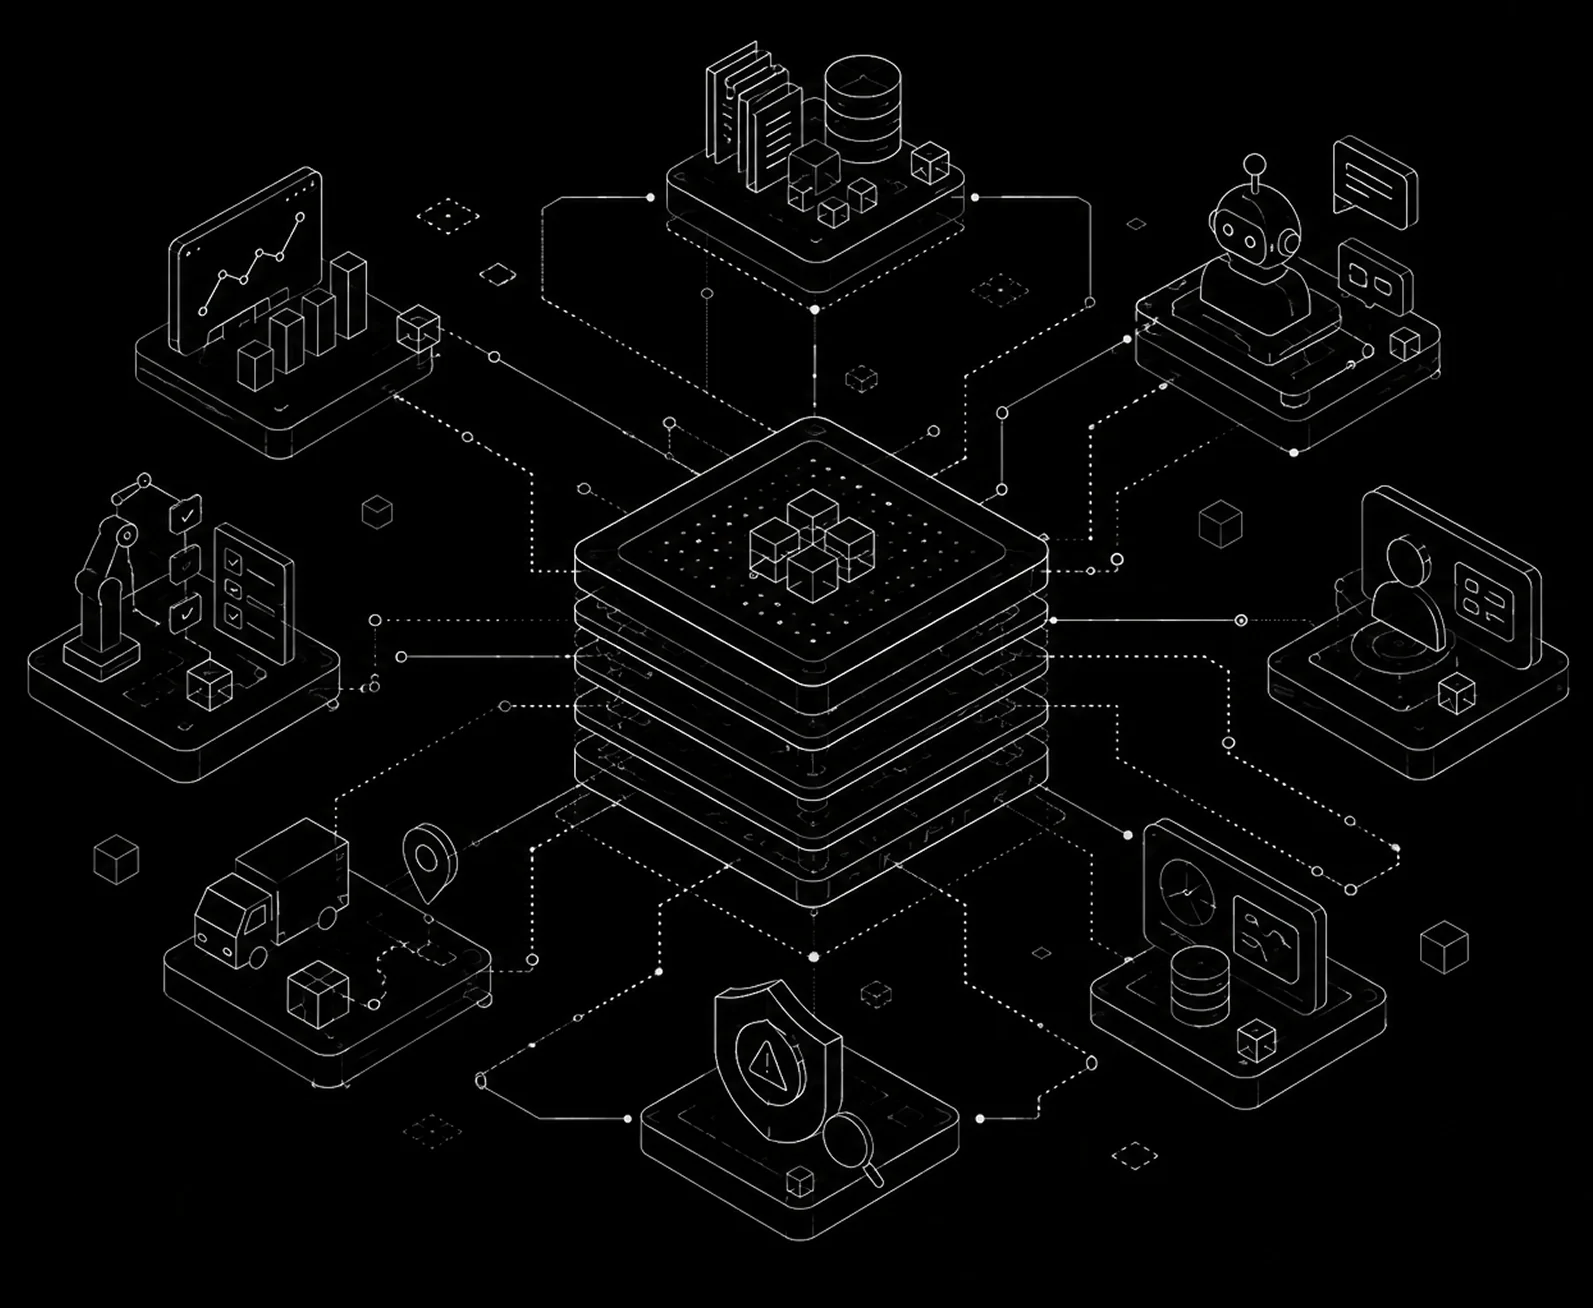
Unify Documents, Knowledge Repositories, Databases, And Enterprise Systems Into Governed AI Knowledge Systems That Stay Current And Access-Aware.
Predictive Analytics:
Prepare High-Quality Historical And Real-Time Data For Forecasting, Demand Planning, And Predictive Models.
AI Agents:
Give Agents Reliable, Contextual, Permission-Aware Access To Enterprise Data Instead Of Static Exports.
Customer Intelligence:
Unify CRM, Behavioral, Transaction, And Interaction Data For A Single View Of The Customer.
AI Data Engineering Across Industries
Financial Services
Unifying transaction, risk, and compliance data for real-time fraud detection and reporting.
Healthcare
Structuring clinical, operational, and patient data for AI while respecting access and privacy requirements.
Manufacturing
Connecting plant, IoT, and supply data for predictive maintenance and production intelligence.
Retail
Bringing transaction, inventory, and behavioral data into one view for forecasting and personalization.
Logistics
Joining shipment, telematics, and carrier data for routing, ETA prediction, and exception handling.
Hospitality
Consolidating property, booking, and guest data for revenue management and guest experience models.
Real Estate
Governing portfolio, lease, and market data so contracts and documents are searchable and usable by AI.
Modern Data & AI Engineering
Technology Stack
Data Processing → Apache Spark, Apache Flink
Streaming → Apache Kafka
Orchestration → Apache Airflow, Prefect
Transformation → dbt


Cloud → AWS, Microsoft Azure, Google Cloud
Data Warehousing → Snowflake, BigQuery, Redshift
Databases → PostgreSQL, MySQL, MongoDB


AI/ML → Python, PyTorch, TensorFlow, Scikit-learn
Vector & AI Data Infrastructure → Vector databases, embedding pipelines, retrieval systems
Our AI Data Engineering Approach
Stage1
Discover
Assess Data Sources, Systems, Business Requirements, AI Use Cases, And Existing Architecture.
Stage2
Architect
Design A Scalable Data Architecture Aligned With AI, Analytics, Governance, And Operational Needs.
Stage3
Engineer
Build Pipelines, Integrations, Transformation Layers, And AI-Ready Data Workflows.
Stage4
Validate & Govern
Implement Data Quality, Observability, Security, Lineage, And Access Controls.
Stage5
Operate & Scale
Monitor Performance, Optimize Infrastructure, And Scale The Platform As AI Adoption Grows.
Why Enterprises Choose Redblox for AI
Data Engineering
AI-First Engineering Mindset, Applied To The Data Layer From Day One, Not Bolted On Afterward.
Enterprise Architecture Expertise Across Cloud, Hybrid, And Legacy Environments.
Data Engineering And AI Engineering Under One Partner, Not Two Disconnected Vendors.
Deep Integration Experience With The Enterprise Systems You Already Run On.
Architecture Built To Scale With Data Volume And AI Adoption, Not Just Today’s Workload.
Security And Governance Designed From The Start, Not Retrofitted Later.
Production-Focused Engineering: Pipelines Built To Run Reliably, Not Just Demo Well.
A Direct Line From Data Infrastructure To The AI Applications & AI OS Built On Top Of It.
Power Your AI Operating System
With an Intelligent Data Foundation
An AI operating system requires more than models and agents to function. It requires trustworthy enterprise data, dependable integrations, real-time data flows, controlled access, contextual knowledge, AI-ready pipelines, observability, and scalable infrastructure.
AI data engineering is what makes this possible. It becomes the underlying data layer that allows AI agents, workflows, applications, and enterprise automation to function consistently rather than failing when they encounter real corporate data.
Enterprise Data
Data FoundationTrusted • Secure
AI Operating System
Reliable AI Outcomes
What Better Data Engineering Enables
Faster AI deploymentBetter data qualityLower operational complexityReduced data silosReal-time business visibilityScalable AI infrastructureStronger governanceMore reliable AI outputsBetter model readinessFaster decision-making
Frequently Asked Questions
Build the Data Foundation Your AI Strategy Needs
Whether you’re modernizing legacy infrastructure, preparing for GenAI and RAG, or scaling AI across the business, it starts with a data
foundation you can trust. Let’s talk about your data architecture, AI readiness, and where Redblox can help.
Fill your details below and get in touch with our domain experts